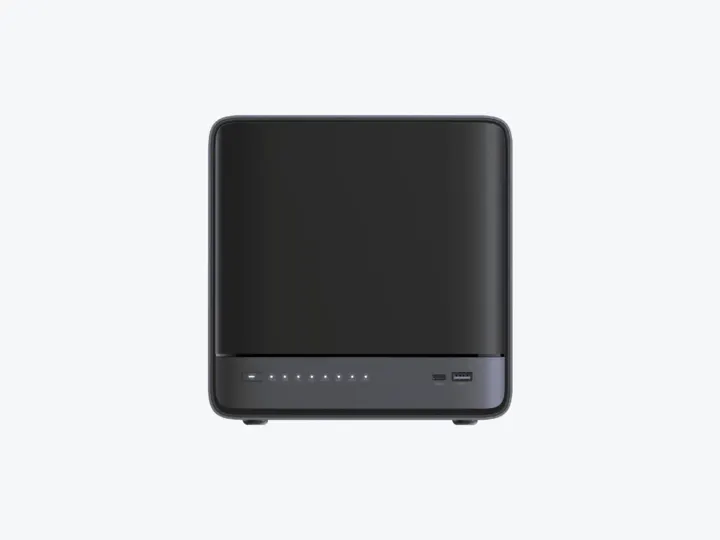
A 5GbE client limited storage tests: the mixed 11GB set reached about 145 MB/s, 165 MB/s with cache and 202 MB/s in TrueNAS without cache. Model-specific AI results require the listed runtime and memory conditions.
Test setup, measurements & limitations
IT Pro N5 Max review (64GB LPDDR5x unit)
Tested: N5 Max, Ryzen AI Max+ 395, 64GB unified memory. Storage: 5× 2TB WD Red Plus RAID 5 plus SSDs (RAID 1, later one SSD as read cache). Client 5GbE bottleneck on a 10GbE QNAP switch. MinisCloud then TrueNAS reinstall.
Applies to: Direct to N5-MAX-39561US (64GB). Related only to N5-MAX-39511US (128GB) — GPU memory ceiling and model-size claims do not automatically scale.
- MinisCloud felt like an early release; a lockable disk-caddy lever snapped during setup.Source location: Setting up / Features and apps
- TrueNAS storage was faster than MinisCloud on the mixed 11GB dataset.Source location: Storage performance
- GPU allocation was about 30GB by default and up to 48GB in BIOS. A 70B-parameter model requiring more than 45GB at 4-bit plus context leaves little room; model parameters are not gigabytes.Source location: AI Performance
Measurements reported by the reviewer| Measurement | Result | Conditions & source location |
|---|
| PCMark 10 Data Drive | 843 | 5GbE client bottleneckStorage performance |
|---|
| ATTO / MinisCloud | >590 MB/s from 64KB ops; reads ~560 MB/s | Nearly saturating the 5GbE testerStorage performance |
|---|
| Windows mixed 11k-file set | ~145 MB/s; ~165 MB/s with SSD cache | Approximately 11GB, around 11,000 small files plus hundreds of medium/large files; disk and SSD volumes in MinisCloud; 5GbE client.Storage performance |
|---|
| TrueNAS mixed 11GB write | ~202 MB/s; full set in <1 minute | Disk volume, no SSD cacheStorage performance |
|---|
| Llama 3.2 3B | ~72 tokens/s | Llama 3.2 3B on the reviewed 64GB system; result depends on inference runtime and precision. The article’s internally incorrect RTX 5070 VRAM comparison is not adopted.AI Performance |
|---|
| gpt-oss 20B | ROCm 40+ t/s; NPU 18.9 t/s; Vulkan MXFP4 72.9 t/s | Quantization/backend specificAI Performance |
|---|
| Gemma 4 inference | MoE 26B about 44 tokens/s; dense 31B about 9 tokens/s | Distinct models; not a controlled architecture-only comparisonAI performance |
|---|
Limits to keep in mind
- 5GbE client, not a full 10GbE pair test.
- 64GB SKU only.
- Do not convert AI tokens/s into NAS folder scores.
- No controlled combined AI-and-storage concurrency benchmark is documented.
- Model/runtime/quantization choices materially change inference speed; GPU allocation is smaller than total unified memory.